The quick answer
Start preparing for AI browser agents by making the website's real tasks understandable: clear destinations, correctly named controls, visible state changes and honest completion messages. Evaluate WebMCP for a specific workflow when its current support fits the project. An emerging integration cannot replace a task that already fails for the person using the website.
Start preparing for AI browser agents by making the website's real tasks understandable: clear destinations, correctly named controls, visible state changes and honest completion messages. Evaluate WebMCP for a specific workflow when its current support fits the project. An emerging integration cannot replace a task that already fails for the person using the website.
Separate browser tasks from AI search visibility
An AI browser agent may navigate pages and interact with controls on someone's behalf. That creates a different review question from whether a search feature links to an article. A page can be discoverable while its enquiry journey is difficult to operate.
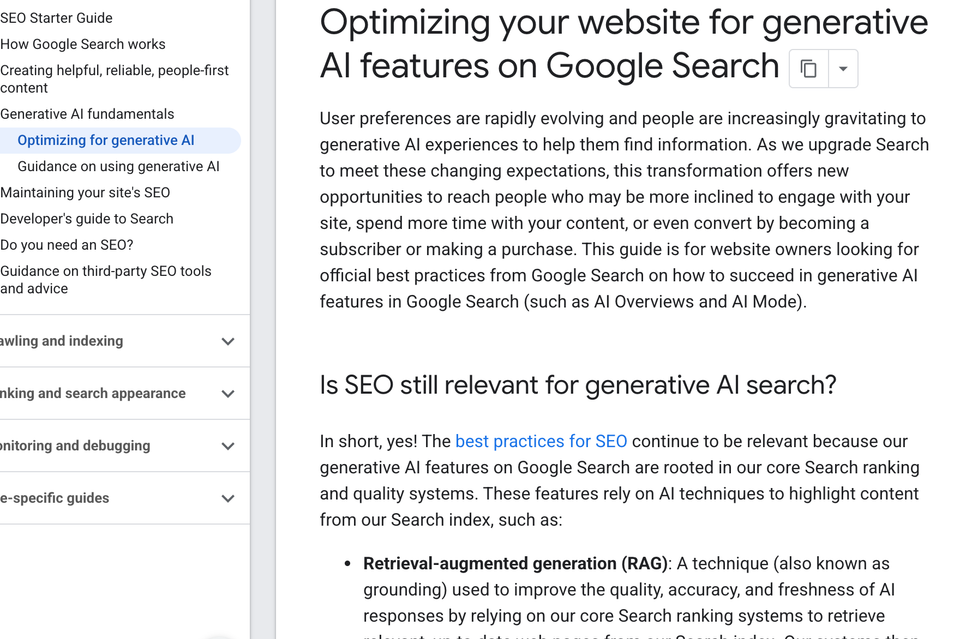
The Google AI search visibility guide covers discovery and reporting. This guide focuses on a website task, the interface signals around it and whether a proposed integration is worth evaluating. It does not claim that adding agent support improves rankings.
Before choosing a tool, write down the intended task and where it ends. Finding a service, preparing an enquiry and sending that enquiry are separate outcomes. Decide which outcome the visitor actually requested.
What current documentation says about WebMCP
Chrome's WebMCP documentation, retrieved on 2 November 2026 with an October 2026 update date, describes a proposed web standard for exposing structured website tools to agents. It documents JavaScript and form-annotation approaches, an origin trial and local development controls.
Those are reasons to evaluate a bounded use case, not evidence of universal browser or agent support. The documentation also describes limitations around browser workflows and tool discovery. Check the current target environment before committing delivery scope; this article is not a hands-on WebMCP benchmark.
Ask a developer to record the supported browser, agent or client, feature status and fallback behavior for the actual project. Do not promise a working integration solely because an API appears in documentation or a demonstration looks convincing.
Make the task legible before adding tools
web.dev's agent-friendly website guidance explains how agents may use rendered images, the DOM and the accessibility tree. It recommends clear semantic controls and a stable interface. This supports a practical starting point: inspect the built task rather than judging the homepage screenshot alone.
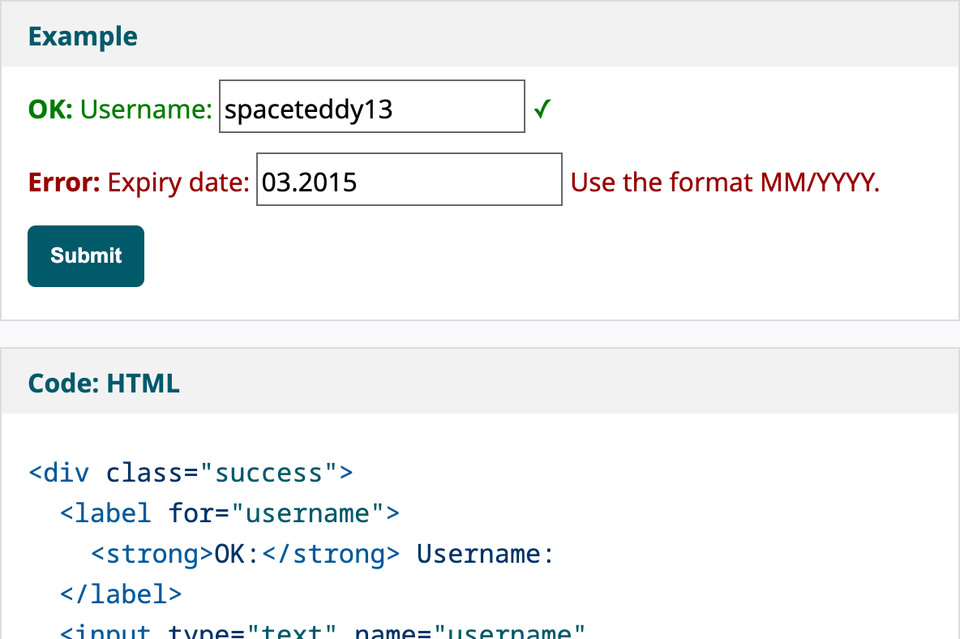
For each important action, record the destination or command, visible label and implemented role. Check that a label identifies the right field, a link leads where it promises and a command communicates its result. The button-label guide provides a focused wording review.
Keep group context visible. If the page offers several products or services, a repeated action must clearly belong to the intended item. A list of generic Select controls leaves an important relationship unresolved.
A fictional plant-shop enquiry task
Consider a fictional shop that receives requests about plant availability. Its proposed task is to find an approved product page and prepare an enquiry for the visitor to review. This is an illustrative planning example, not an observed client workflow or a completed agent test.
The page needs an unambiguous product identity and current, approved availability information. The enquiry should retain the selected item, explain what information is needed and show what will happen next. If availability is not known, the wording should say that an enquiry requests confirmation rather than claiming stock has been reserved.
Record the completion boundary: the visitor can review the prepared message before choosing to send it. Preparing a request should not silently become a purchase or a sent message. Define that boundary as part of the product's actual task, then evaluate how a chosen integration respects it.
The photograph on this guide is AI-generated and fictional. It illustrates a shop owner reviewing a digital task; it is not evidence of a real business using an agent.
Review loading, failure and completion separately
An agent or human needs to distinguish an action that is still processing from one that completed or failed. Start by listing the actual states with the implementer. Agree what evidence supports each success message.
For an enquiry, a displayed message and confirmed delivery to the intended destination are different observations. A timeout may leave the outcome uncertain. Write the recovery path around what the system actually knows rather than always telling someone to submit again.
Use the website error-state worksheet to capture the trigger, known result, recovery action and repeat-check evidence. The error-message guide explains how to keep that copy useful and accurate.
Choose one bounded integration experiment
If the ordinary journey works and there is a reason to evaluate WebMCP, choose one small task. Record its inputs, result, permitted scope, required user decision and fallback when the feature is unavailable. Keep credentials and private test records in the project's approved environment.
An experiment needs a named owner and a repeatable check. Record the actual browser and agent versions, starting page, task instruction, inputs and observed result. A successful demonstration in one environment does not establish support for every customer or every agent.
Avoid changing the whole site's interaction model around an unmeasured assumption. A well-defined experiment can reveal whether structured tools address a real problem in this particular workflow.
Keep an evidence record that another person can repeat
Separate four kinds of evidence: what the public documentation describes, what the website implements, what was observed in a particular test and what the business has approved. This prevents a vendor's capability statement from becoming an invented project result.
A useful finding names the task, environment, obstruction and observed outcome. It might identify a mislabeled field or a completion message that appears before the owner can confirm delivery. Assign the issue to the relevant content or implementation owner and record the repeat-check result.
Use the navigation planning worksheet for the path to the task and the form planning worksheet for its input and submission contract. These ordinary records remain useful whether the task is carried out manually or through an emerging integration.
Sources and scope
Sources checked 2 November 2026. This is a practical evaluation framework, not a tested agent integration or a claim of universal support. No accessibility certification, conversion improvement or search-ranking outcome is promised.
The Blitz Studio team
We design brands, build websites and engineer digital products.
Talk about your next project